India links synthetic-media labels to faster removal and platform liability
India has tightened its framework for AI-generated and manipulated content under amendments to the Information Technology intermediary rules. Permissible synthetic content must carry clear labels and traceable metadata. The rules expressly cover AI-generated child sexual abuse material, non-consensual intimate imagery, impersonation and other harmful synthetic content. Platforms must remove unlawful material within three hours of a valid government or court order, while complaints involving nudity or impersonation require action within two hours. Larger platforms also face proactive detection, compliance-reporting and law-enforcement assistance obligations.
Why visual creators should care
This combines disclosure, provenance and removal duties inside one platform-liability framework. For creators whose faces, performances or photographs are misused, the shortened timelines may be more important than the label itself because synthetic material can accumulate enormous reach before a conventional complaint is reviewed.
Practical takeaway
When filing an Indian platform complaint, identify the impersonation or unlawful use precisely, preserve the URL and timestamps, submit genuine source files and state whether the synthetic material includes intimate content, a child, identity misuse or another time-sensitive category. For legitimate AI work aimed at Indian audiences, preserve the visible label and traceable metadata attached at publication.
What to watch next
Watch how platforms implement the two- and three-hour deadlines, what evidence they require from complainants and whether automated preventive measures produce significant false positives against legitimate creative work.
Sources
Adobe’s ChatGPT plugin turns a conversation into a complete creative-production route
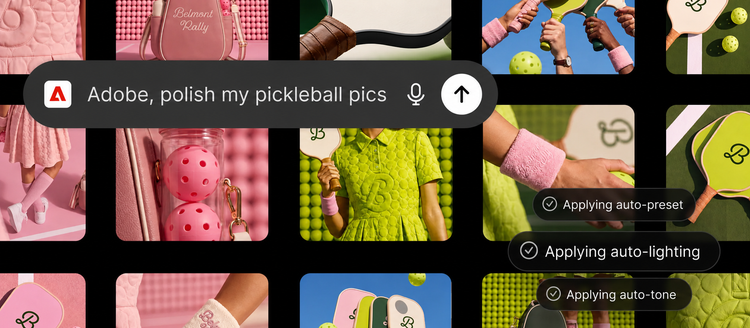
Adobe has introduced a unified plugin for ChatGPT that draws on more than 70 tools across Photoshop, Firefly, Premiere, Lightroom, Illustrator, InDesign, Adobe Stock, Express, Acrobat and other services. Adobe says users can upload campaign photographs, apply a consistent visual treatment, create mockups, turn long-form video into social edits, generate designs and save finished assets to Creative Cloud without leaving the conversation. Signing into an Adobe account unlocks generative capabilities and access to Creative Cloud files.
Why visual creators should care
The production interface is no longer necessarily the application that performed the edit. A creator may describe the outcome in ChatGPT while Adobe automatically chooses and coordinates the underlying tools. That makes a record saying only ‘edited in Photoshop’ or ‘made in ChatGPT’ increasingly incomplete.
Practical takeaway
For client work, record both the conversational interface and the Adobe tools or generative services that acted on the media. Before uploading confidential photographs or footage, confirm account, storage and client-permission requirements. Preserve the original files and export history separately from the chat.
What to watch next
Watch whether Adobe exposes a durable per-asset activity log showing which tools and models acted on each file, and whether Content Credentials identify the complete workflow rather than only the final Adobe service.
Sources
A creator can lose control of her performance even when the copied face belongs to someone else
A documented impersonation case involving creator Paige Davis shows a form of synthetic appropriation that ordinary face-matching systems may miss. A reposted video retained her voice, body, clothing, car interior, gestures and sales performance while replacing only the face. Thousands of ordinary reports were rejected by automated moderation. The video was removed only after Davis submitted a detailed intellectual-property complaint containing identification, timestamps and formal legal information.
Why visual creators should care
Likeness misuse is becoming more modular. A bad actor can replace the face while keeping the commercially valuable part of a creator’s identity: the voice, physical performance, styling, credibility and relationship with the audience. A platform searching only for facial similarity may therefore classify the wrong person as the subject of the video.
Practical takeaway
Document the entire performance when reporting synthetic appropriation. Compare voice, movement, clothing, set, framing, timing and original script as well as the face. Preserve the source upload and use the platform’s intellectual-property or impersonation route when ordinary community-standard reports fail.
What to watch next
Watch whether major platforms broaden likeness detection beyond facial identity and whether removal systems begin treating the unauthorised reuse of voice, body and performance as a single identity claim.
Sources
Deepfake detectors can be attacked together rather than defeated one at a time
An ImageCLEF 2026 research submission created identity-preserving synthetic faces and applied an adversarial attack aimed at 12 deepfake detectors simultaneously. The method reportedly evaded 90% of the organisers’ detectors and 57.6% of participant detectors. The researchers’ own detection system performed strongly on ordinary baseline deepfakes but produced enough false positives on real images to reduce its overall score. They also identified a sharp loss of one detection signal around a particular JPEG-quality threshold.
Why visual creators should care
Detection systems are often evaluated against ordinary generated media rather than media deliberately modified to escape them. A creator, publisher or competition may therefore receive a confident result from a detector that the synthetic file was specifically designed to fool.
Practical takeaway
Do not base an accusation, rejection or takedown on one detector. Preserve the original file, examine provenance, compare known source material and use more than one technical method. Record compression and export history because routine media processing can materially alter detector performance.
What to watch next
Watch independent replication of the evasion rates and whether provider-specific watermarks and signed provenance prove more durable than classifiers trained to recognise visual generation patterns.
Sources
Veo 3 disappears from Runway while the surrounding production API stays in place
Runway’s developer catalogue marks Google Veo 3 as deprecated and states that it was sunset on August 4. Veo 3.1 and Veo 3.1 Fast remain available alongside Runway, ByteDance and other image and video systems. Applications using Runway’s interface may therefore continue functioning while the specific model that previously generated an approved asset is no longer selectable.
Why visual creators should care
A stable API does not guarantee a stable generator. Client teams may discover that they can reopen the application but cannot reproduce the look, motion or behaviour created with the retired model.
Practical takeaway
Log the exact model identifier returned for every approved generation. Preserve final outputs, prompts, reference media and test renders before a model is deprecated. Do not promise repeatability based only on continued access to the surrounding platform.
What to watch next
Watch how long Veo 3 output records remain accessible and whether Runway offers any migration or reproducibility guidance for projects moving to Veo 3.1.
Sources
Europe’s new AI labels do not have to be applied backwards to older media
European Commission guidance says content generated before August 2, 2026 does not need to be labelled retroactively under Article 50. The Commission nevertheless encourages deployers to label older material where doing so is feasible and useful. Systems and content falling within the rules after the application date remain subject to the provider-marking and deployer-disclosure duties already in force.
Why visual creators should care
Agencies and publishers may hold large archives of previously generated campaign images, synthetic presenters or AI-assisted video. The clarification means those files are not automatically non-compliant merely because they lack today’s labels, but republishing or modifying older material may still require a fresh legal and platform review.
Practical takeaway
Record the original creation date of synthetic media. When reusing an older asset, check whether the new publication context creates a separate disclosure expectation under current law, advertising standards, client policy or platform rules.
What to watch next
Watch how regulators treat materially edited or newly republished pre-August 2 content and whether organisations voluntarily label older archives to avoid confusing audiences.
Sources